
NAP Personal Names Transcription
Overview
Global Many-to-Many Identity Transcription & Phonemic Engine
An enterprise-grade identity intelligence solution designed to execute ultra-precise, complex many-to-many phonemic conversions of personal names across disparate global scripts and non-Roman transcription systems.
Concept

Screenshots
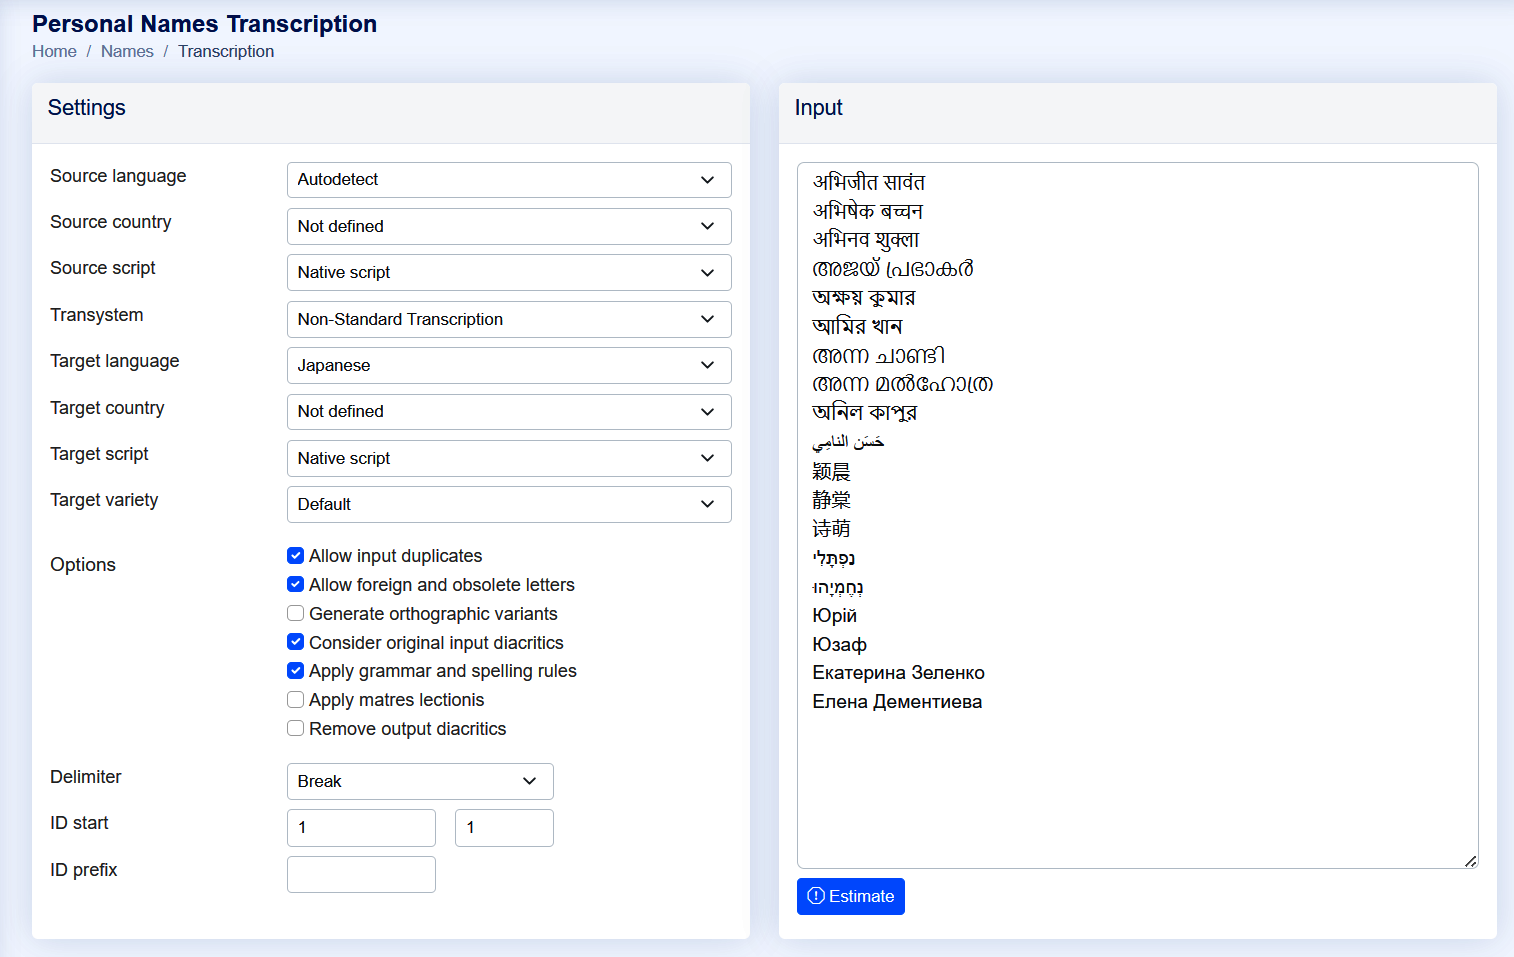
Screenshots

Screenshots
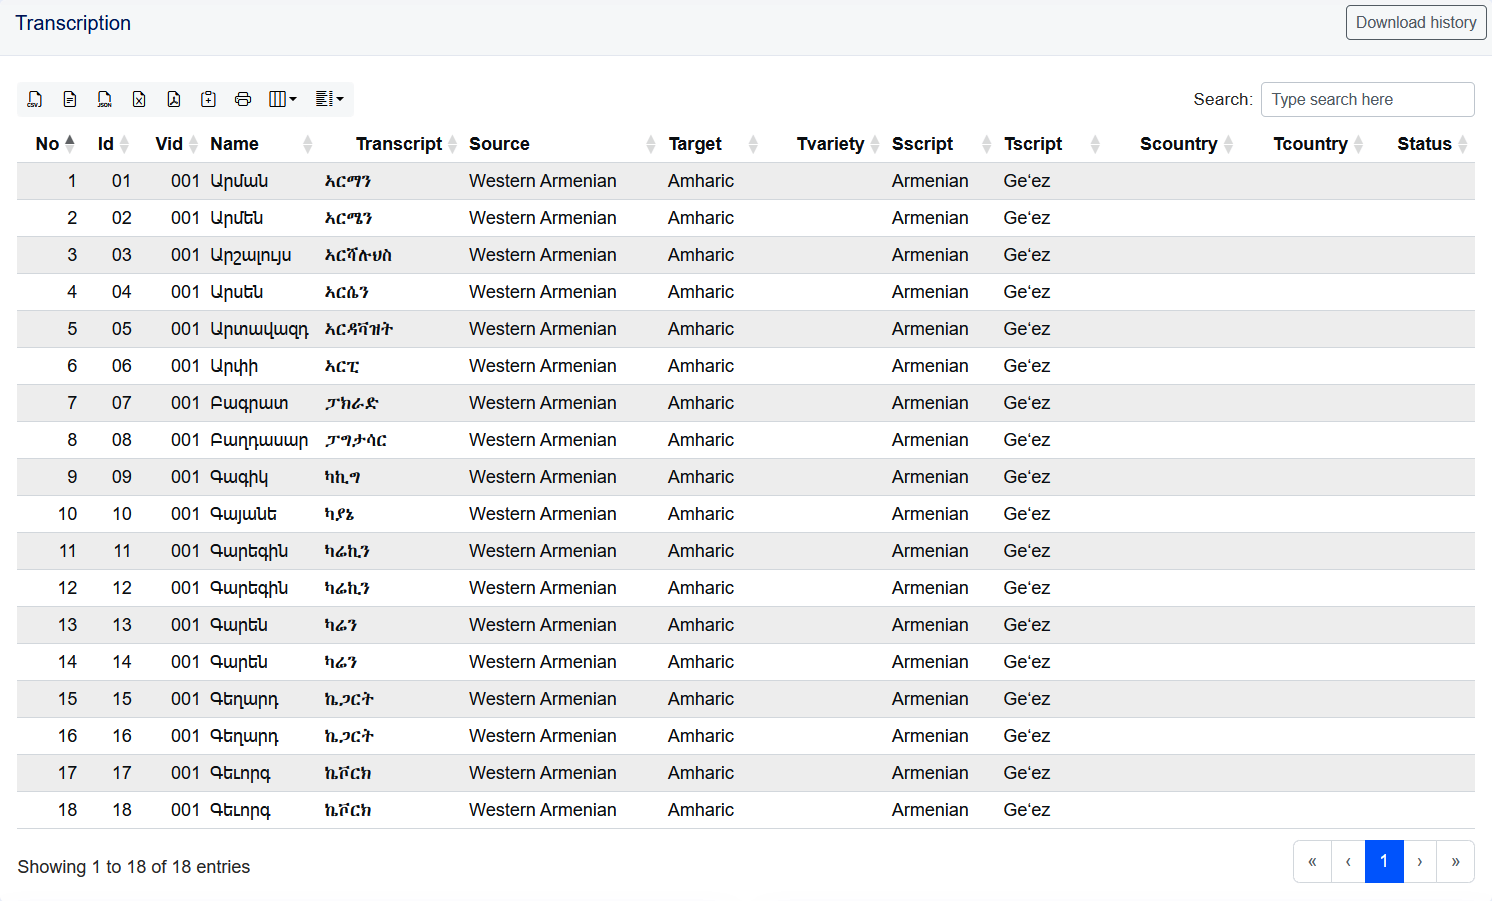
Information
 Desktop application
 NAP Home
Last updated: 18 Jun 2026
Features
Many-to-Many Script Synthesis: Maps and converts personal names across an expansive matrix of 5,000 language pairs and 30 distinct writing scripts simultaneously.
Non-Roman System Support: Deploys 50 advanced transcription and transliteration systems, specifically engineered to handle complex non-Roman target structures seamlessly.
Massive Linguistic Footprint: Processes names across 150 non-Latin languages and 200 countries, featuring deep dialectal calibration for 33 distinct language varieties (including Amharic, Arabic, and Hebrew).
Dual-Mode Phonetic Precision: Synthesizes and matches identity records utilizing synchronized Phonemic and Phonetic processing pipelines to preserve native pronunciation.
Zero-Touch Script Intelligence: Integrated NLP delivers instant language and script auto-detection, eliminating manual pre-sorting of multi-script identity data.
High-Capacity Bulk Ingestion: Ingests unstructured global name databases via Vertical Lists or Separated Values (Comma, Semicolon, Space).
Downstream Delivery & Manipulation: Exports clean, structured identity sheets into 5 core formats (CSV, JSON, XLSX, PDF) with instant UI-level live searching, filtering, and column reordering.
Production-Grade Infrastructure: Integrates into high-speed identity verification pipelines or human workflows via a scalable REST API or an intuitive GUI.